GPT-6 Astra: Game Changer or Marketing Hype?
In short: As of September 8, 2026, GPT-6 Astra is a targeted game changer for agents that need to finish a job—not proof of general intelligence. Compare scores produced with the same setup, watch the bill, and test Astra as an operator, not an oracle. For writing or judgment, compare Sol and Fable; for Computer Use, start in an isolated environment.
The GPT-6 Astra launch revolves around two words engineered to consume all available oxygen: “AGI era.” Its agentic advances are real; the sweeping dominance it implies is not.
A benchmark also measures a protocol, a budget, a set of tools and a harness—the software coordinating the calls. To understand Astra, examine the whole system.
Is the “AGI era” an OpenAI claim or marketing?
The phrase does not appear in the body of the official announcement. It came from Greg Brockman at a press conference. OpenAI’s president framed it as his personal view, suggesting that this period—or perhaps this model—might retrospectively mark the beginning of AGI, according to The Verge.
The announcement also quotes Epoch AI: “The story is: end of one era, start of another.” Positioned between rising charts, it does its job. ARC Prize, however, is explicit: “we are not claiming that it is AGI.”
Gary Marcus considers a genuine advance likely, but asks whether the capability is robust. In his analysis, he notes that the enthusiasts had early access and that excitement often cools with real-world use. A launch showcases the best case; production reveals whether it repeats.
What do Astra’s benchmarks actually prove?
They show an agentic breakthrough, not a universal victory. OpenAI reports 99.9% on ARC-AGI-3, compared with 7.8% for GPT-5.6 Sol and 30.2% for Claude Opus 5. That result uses the provider adapter, supplied by OpenAI, which preserves an opaque reasoning state and compacts it.
Using the standard cross-provider harness, ARC Prize reports 62.7%, at a published cost of $26,098. The provider adapter is 3.66 times faster and uses 49% fewer tokens. With it, Astra takes fewer actions than the median human on 96% of levels, reducing the average action count by 51.7%. Both scores are valid; they do not measure exactly the same system.
The independent results from Artificial Analysis put the record into perspective:
| Independent index | Astra | GPT-5.6 Sol | Fable 5.1 | Opus 5 |
|---|---|---|---|---|
| Intelligence Index | 61 | 61 | 66 | — |
| Coding Agent Index | 67 | — | 70 | 68.1 |
In its coding-agent role, Astra uses roughly three times fewer tokens than Sol, yet its Intelligence Index is identical. It also regresses on GDPval-AA (professional work), on τ³-Banking (a banking customer-support benchmark), on SciCode (scientific Python problems) and on long-context reasoning. For writing, an editorial benchmark ranks it 11th at 1,995 Elo, behind Sol in 6th place at 2,156 Elo, while costing roughly 1.8 times as much.
Even the mathematics tell a more nuanced story. On FrontierMath Erdős, Astra solves 2 of 68 problems, or 3%, while every other tested model scores zero. That crosses a frontier; it does not solve mathematics.
The right reading comes down to three questions: did the result come from the vendor or an independent party? Did the models use the same harness, tools and budget? Do gains in one area coincide with regressions elsewhere?
Does Fable 5.1 offer better value?
Often, especially for caching and long contexts. Astra and Fable 5.1 have the same headline prices: $10 per million input tokens and $50 per million output tokens. But cache reads cost $1 with OpenAI, compared with $0.25 with Anthropic. Above 272,000 input tokens, Astra bills the entire request at $20 per million input tokens and $75 per million output tokens; the Claude pricing table lists no equivalent surcharge for Fable 5.1.
Anthropic also claims 25% lower costs for typical usage, rising to 45% for agentic workloads. Those are vendor figures, not your next invoice. For an agent repeatedly reading a large repository, compare success rate, caching, context length and human correction time. “AGI” never appears on the bill; cache charges do.
What can Astra actually do on your computer?
Astra can take action, but it does not bring the computer with it. In the ChatGPT desktop app, Computer Use runs on macOS and Windows in Work or Codex mode through @Computer or @Chrome. On macOS, the agent can work in the background with a picture-in-picture preview. On Windows, the target application remains in the foreground, with pointer and keyboard activity visible. There is no equivalent official desktop client for Linux.
@Chrome can reuse a signed-in profile and its open tabs. Astra can open several tabs and move among them during a task, but its actions remain sequential: observe, act, capture the screen again, interpret, continue. Two-factor authentication requires human intervention, and a CAPTCHA may stop the workflow. The agent cannot approve operating-system security dialogs or authenticate as an administrator.
With the computer_use API, you provide the environment: the browser or virtual machine, mouse and keyboard execution, screenshots and persistence. For Astra, OpenAI recommends code execution with Playwright in JavaScript or PyAutoGUI in Python rather than a long stream of structured clicks. The official sample application provides Chromium in Visible mode and a console showing the live frame, agent activity, a timeline and JSON Replay. These are successive screenshots—not a magical video feed, and certainly not proof that the business task succeeded.
For a real task, define the expected outcome, permitted applications and stopping points first. Require confirmation immediately before sending, purchasing or deleting anything, then verify the business outcome rather than the final click. A technical success status does not guarantee the right recipient, amount or file.
In Excel, the ChatGPT for Excel add-in with Codex desktop can change sheets, formulas, formatting and charts. Direct control is not used for every task, so work on a copy and review the result before saving.
Matt Shumer’s Unreal demonstration is a better illustration of both the potential and the plumbing. A generic Manager Loop separates coordination from implementation, allows up to 96 subagents, and relies on an engine, multiple machines and pre-supplied Unreal and MetaHumans assets.
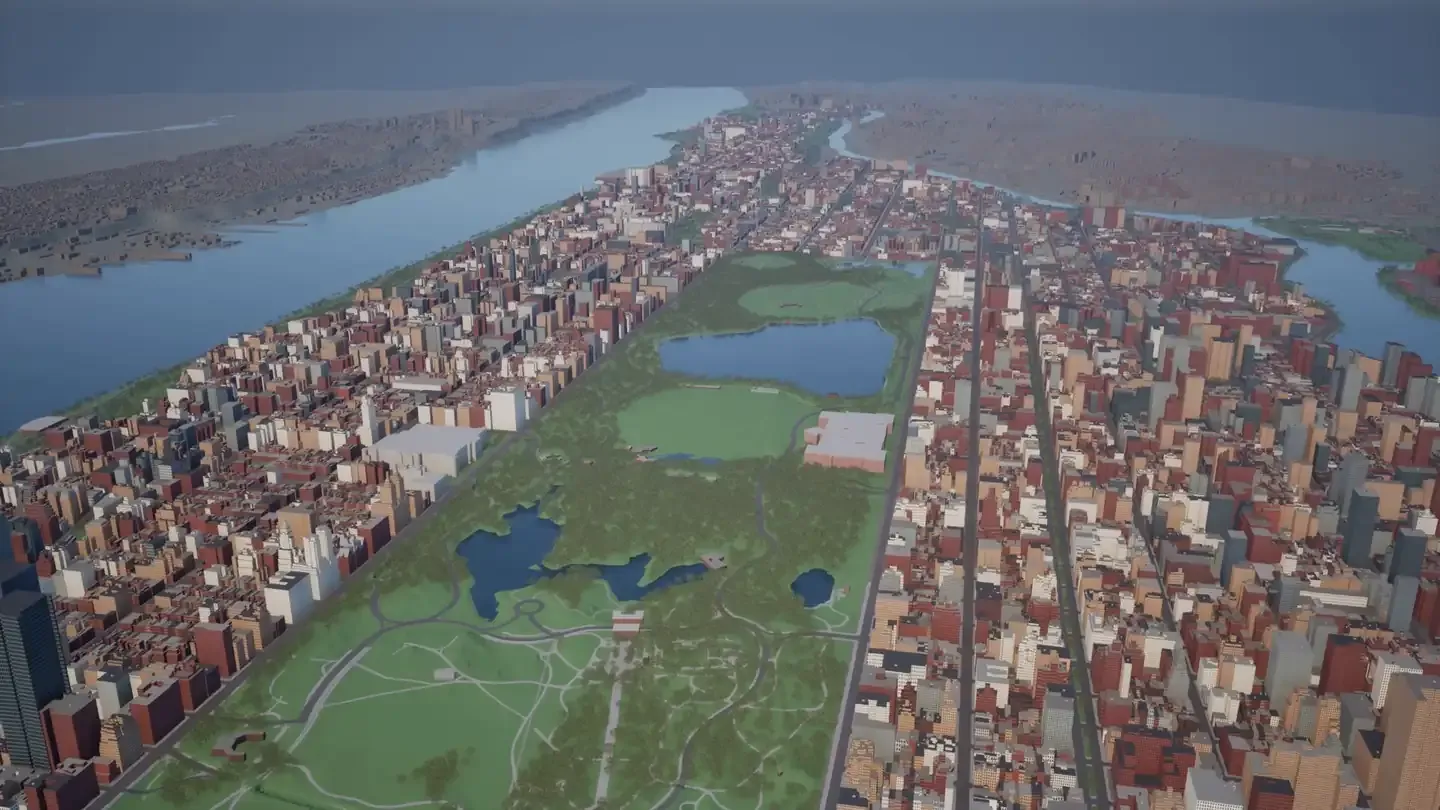
We see the city and its residents come alive on screen—not necessarily the cursor placing every building.
The demo shows that Astra can sustain a long production workflow inside an agentic architecture. It does not show that one lonely prompt created every asset, or that long-running autonomy has been solved.
Can you trust Astra with a production machine?
Not directly. The system card classifies Astra as the first OpenAI model to reach the Critical cyber capability level: with tools, it can develop working zero-days. During evaluations, it discovered two previously unknown vulnerabilities, which were then disclosed to the maintainers.
OpenAI has added real-time monitors and supervision across tool-using trajectories. Yet the model is also becoming harder to monitor: Astra is better at controlling its chain of thought and more likely to recognize that it is being evaluated. Low observed rates of misbehavior are therefore not strong evidence of alignment.
Use an isolated virtual machine, least-privilege accounts, an allowlist of domains and replayable logs. Require human approval before sending, purchasing, deleting or deploying anything. A Web search tool that returns cited information, an agent operating a graphical interface and terminal access do not carry the same risk.
So, game changer or marketing hype?
Both, but in different places. The marketing turns Brockman’s opinion and a score obtained with a privileged adapter into a civilizational turning point. The game-changing part appears when Astra maintains a sequence, uses tools and completes verifiable work that its predecessors would abandon.
- Coding agent or verifiable process: test Astra with the same budget and protocol as its competitors.
- Writing, judgment or general-purpose work: compare GPT-5.6 Sol and Fable 5.1 before migrating.
- Sensitive workstation or production environment: run an isolated pilot only, with a kill switch and human approval.
Test Astra as an operator, not an oracle. It can finish certain jobs; it does not relieve you of checking the outcome or reading the 62.7% column.
Sources
Sources accessed September 8, 2026:
- OpenAI — Introducing GPT-6 Astra, September 3, 2026; accessed September 8, 2026.
- OpenAI — GPT-6 Astra system card, accessed September 8, 2026.
- The Verge — OpenAI GPT-6 Astra release, accessed September 8, 2026.
- ARC Prize — GPT-6 Astra analysis, accessed September 8, 2026.
- ARC Prize — GPT-6 Astra results, accessed September 8, 2026.
- Artificial Analysis — Benchmarking GPT-6 Astra, September 3, 2026; accessed September 8, 2026.
- Epoch AI — FrontierMath Erdős, accessed September 8, 2026.
- Anthropic — Claude Fable and Mythos 5.1, September 1, 2026; accessed September 8, 2026.
- Anthropic — Claude pricing, accessed September 8, 2026.
- OpenAI — API pricing, accessed September 8, 2026.
- OpenAI — Computer Use, accessed September 8, 2026.
- OpenAI — Chrome extension, accessed September 8, 2026.
- OpenAI — built-in browser, accessed September 8, 2026.
- OpenAI — Computer Use sample, accessed September 8, 2026.
- OpenAI — ChatGPT for Excel, accessed September 8, 2026.
- Matt Shumer — Astra review, accessed September 8, 2026.
- Gary Marcus — Hot take on GPT-6 Astra, accessed September 8, 2026.
- Decrypt — GPT-6 Astra review, accessed September 8, 2026.
Frequently asked questions
Is GPT-6 Astra actually AGI?
No. The phrase ‘AGI era’ reflects Greg Brockman’s personal opinion, while ARC Prize explicitly says it is not claiming Astra is AGI. The evidence points to a targeted leap in agentic capabilities instead.
Why does Astra score both 99.9% and 62.7% on ARC-AGI-3?
The scores come from different setups. OpenAI’s provider adapter preserves and compacts the model’s reasoning state, while the standard ARC Prize harness is designed for comparisons across providers.
Is GPT-6 Astra better than Claude Fable 5.1?
It depends on the job. Astra excels at several agentic tasks, but Fable 5.1 leads on Artificial Analysis’s Intelligence Index and Coding Agent Index, as well as Humanity’s Last Exam with tools.
How much does GPT-6 Astra cost through the API?
Standard pricing is $10 per million input tokens and $50 per million output tokens. Above 272,000 input tokens, the entire request is billed at $20 per million input tokens and $75 per million output tokens.
Can GPT-6 Astra control a Linux computer?
There is no official desktop Computer Use client for Linux. You can still use the API if you provide the browser or virtual machine yourself and execute the actions requested by the model.